


Most AI SEO advice focuses on what you write. Before any of that matters, there is a quieter question: can the systems behind AI answers actually read your pages? Many sites fail this test without knowing it, and no amount of strong content fixes a locked door. This guide covers the technical layer that Sarkar SEO checks first when auditing a site for AI search.
Why this layer is easy to miss
For years, technical SEO meant satisfying Googlebot. That is no longer the full picture. One industry audit framework puts it plainly: a site now has at least a dozen additional non-human visitors, including crawlers that train models and power AI search results. Your existing setup was probably written with Google and Bing in mind, so it may treat the newer bots badly, or not at all. searchenginejournal
Training bots versus search bots
The most useful distinction is the purpose of each crawler. They are not one group, and treating them as one group is described as the most common mistake.
- Training crawlers collect material to build models. Examples include GPTBot and ClaudeBot.
- Search crawlers build the indexes that answer engines query when responding. OAI-SearchBot, Claude-SearchBot and PerplexityBot fall in this category.
- User-triggered fetchers retrieve a page when a person asks about it. ChatGPT-User and Perplexity-User are examples.
The consequences differ. One analysis states that blocking training crawlers costs very little, while blocking search crawlers removes you from the answer entirely. OpenAI’s own wording, as quoted there, is that sites opted out of OAI-SearchBot will not appear in ChatGPT search answers.
Publishers appear to understand this split. A review of roughly 4,000 robots.txt files found GPTBot was disallowed 2.33 times for every allow, while OAI-SearchBot ended up net allowed. Whether to block training is a business decision about your content. Blocking search access is usually an accident.
Check one: your robots.txt rules
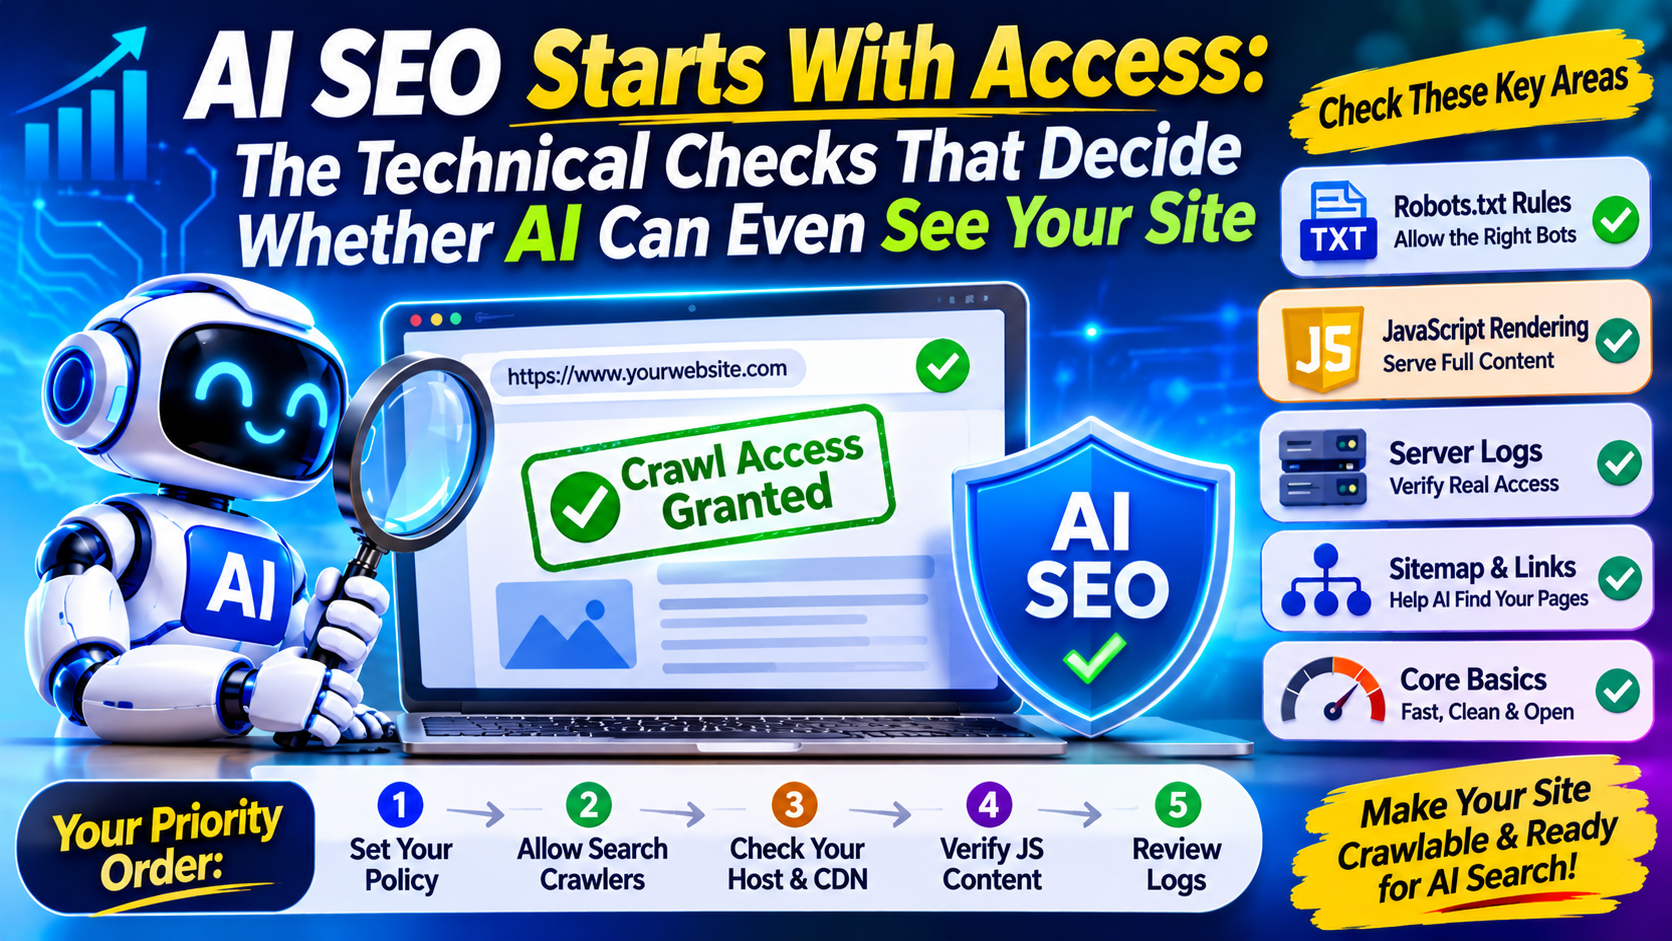
Open your robots.txt file and search for each AI crawler name. Look for three problems:
- A broad wildcard rule that accidentally catches search bots along with training bots.
- An explicit block on a search crawler you actually want.
- Missing rules for subdomains. Robots.txt applies per subdomain, which is described as the most common silent gap.
A sample approach many sites use is to disallow training bots while allowing search bots. If you take that route, test it, because rules are easy to mistype.
Check two: whether the rules are actually enforced
A rule in a file does not guarantee the outcome you intended. One agency reports that HasData tested 10,894 domains in July 2026 and found 39.5% of GPTBot bans in robots.txt were not being enforced. The same source notes that Search Engine Land found a hosting provider rate-limiting AI crawlers at platform level, beneath anything customers could see or change.
So treat robots.txt as a statement of intent. Your server logs, and your CDN or firewall settings, tell you what really happens. Security tools set to block unknown bots can quietly shut out legitimate AI search crawlers.
One caution on user-triggered fetchers. ChatGPT-User and Perplexity-User state in their own documentation that robots.txt may not apply to them. A robots.txt block may therefore not stop every AI retrieval of a page. If you need something kept private, use authentication, not a text file.
Check three: JavaScript rendering
This is the issue most likely to surprise a marketing team. Googlebot renders JavaScript, so a client-side app can rank perfectly well. Several AI crawlers behave differently. One source states that Googlebot, Bingbot and Applebot run JavaScript, but GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot and PerplexityBot read only the HTML the server sends. Another says four of six major crawlers fetch static HTML only, making server-side rendering a requirement for AI search visibility. clearwateragencysearchenginejournal
Treat that wording with some care. These claims come from industry write-ups, and crawler behaviour can change, so confirm against each company’s current documentation. The practical test is simple. Fetch a key page without running scripts, using a command-line request or the “view source” option, and check whether your headline, body copy, prices and links are all present. If the page is an empty shell, a reachable page can still be invisible to some retrievers.
The fix lives in how the page is built. Server-side rendering solves most of this, though it adds load to your server. Static generation or pre-rendering for important pages are common alternatives.
Check four: your logs
Server logs are the only direct evidence of who visited. Filter them for the main AI user-agent names and note which pages they request, how often, and whether they receive successful responses. A crawler that is allowed but never appears is a different problem from one that is blocked, and robots.txt cannot distinguish between the two. Missing visits can point to rate limits, poor internal linking or a weak sitemap.
Check five: the basics still count
Clean sitemaps, working internal links, fast responses and consistent status codes help every crawler. If important pages sit behind login walls, pop-ups or endless redirect chains, machines will struggle just as people do.
A simple priority order
If time is limited, work in this order:
- Decide your policy on training versus search access.
- Make sure search crawlers are allowed on every relevant subdomain.
- Confirm your host, firewall and CDN are not blocking them.
- Verify that key pages show full content without JavaScript.
- Review logs monthly.
What this will not do
Access is a precondition, not a ranking factor. Being crawlable does not mean being cited. It only means you are eligible to compete on content quality, authority and relevance. Be wary of anyone promising guaranteed AI citations because of a robots.txt edit. Some success stories online, such as claims of very large referral gains after pre-rendering, come from single anecdotal posts and should not be treated as typical.
