


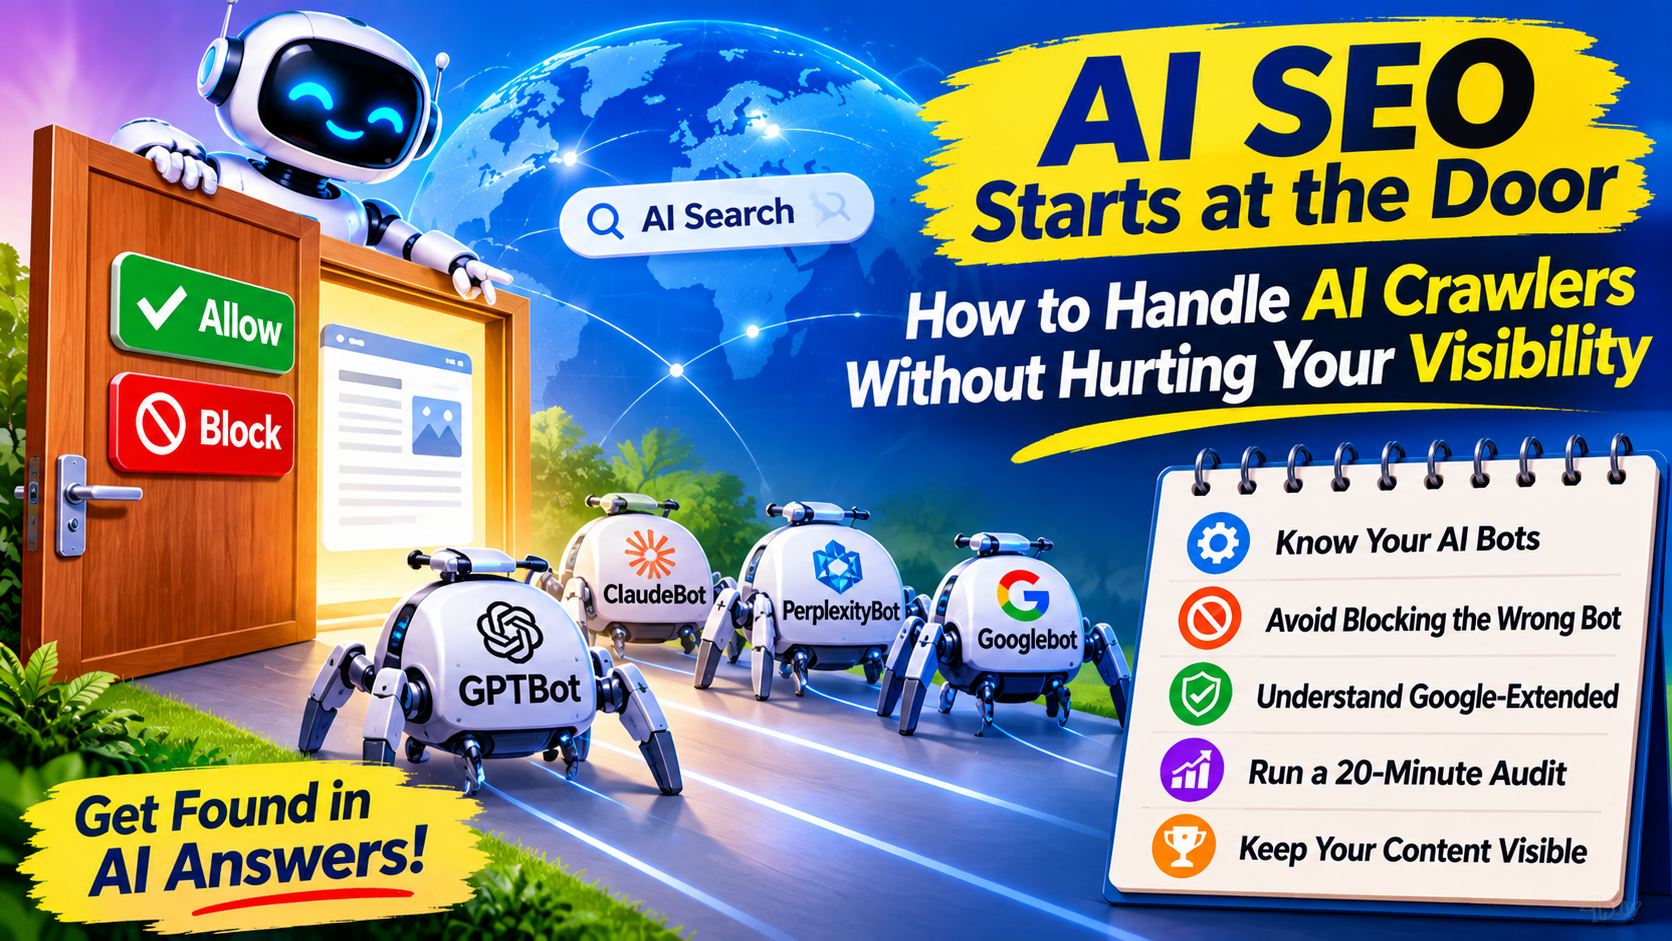
Before any AI SEO assistant can cite your page, something has to read it. That “something” is a crawler, and many sites are accidentally turning crawlers away.
A single line in a robots.txt file, or a toggle in a security dashboard, can make a site invisible to some answer engines. This guide explains the crawler landscape and gives you a decision framework that doesn’t rely on guesswork.
Not All AI Bots Do the Same Job
Treating “AI bots” as one group is the most common mistake. One guide separates them into two types: training crawls, where content is collected for future model versions, and answer crawls, where content is fetched on the spot to generate an answer and is cited as a source.
A third type exists too: bots that act when a user asks. The Superblog crawler guide lists these tokens by operator:
- OpenAI: GPTBot for model training, OAI-SearchBot for the ChatGPT search index and citations, and ChatGPT-User for user-initiated fetches.
- Anthropic: ClaudeBot for training, Claude-SearchBot for the search index, and Claude-User for user-initiated fetches.
- Perplexity: PerplexityBot for search results, plus Perplexity-User.
Naming conventions matter because the token is the part you match on, both in robots.txt and in log analysis; version numbers change, the token does not.
The Costly Mistake: Blocking the Wrong Bot
Many site owners add a blanket opt-out for AI. One technical write-up warns that a blanket “User-agent: GPTBot / Disallow: /” feels like a reasonable AI opt-out, but leaves OAI-SearchBot untouched and still crawling. The result may be the opposite of what you wanted: you think you’re protected, but the search crawler continues.
The reverse also happens. Blocking GPTBot stops AI training, while blocking OAI-SearchBot removes you from ChatGPT Search. The directives are different, and so are the consequences.
There is also a quieter failure. One checklist warns about blocking crawlers at the CDN or WAF layer, such as a Cloudflare “Block AI Bots” toggle, where robots.txt looks fine but the request never reaches your origin. If you use a security layer, check its settings and not only your text file.
The Google-Extended Confusion
Google-Extended is widely misunderstood, and sources disagree about it. One checklist claims that blocking it removes you from Gemini and Google AI Overviews entirely. Other sources say the opposite. A technical analysis states that Google-Extended is a robots.txt control token that governs whether content can train Gemini and Vertex AI generative APIs, with no effect on Google Search or on AI Overviews ranking signals. A separate review of Google’s documentation adds that Google describes it as a control for training and grounding in some other Google AI systems, not as an AI Overviews or AI Mode opt-out. ThinkProfits logo +2
The safer reading is the one that matches Google’s own documentation. Eligibility for AI Overviews depends on normal Search indexing and snippet rules, as covered earlier in this series. Before changing anything, read Google’s current crawler documentation yourself, and don’t rely on any third-party summary, including this one.
A Decision Framework
Sarkar SEO starts crawler decisions with two questions, because the answers differ by business.
Question 1: Do you want to appear in AI answers? If yes, retrieval bots such as OAI-SearchBot and PerplexityBot need access, and blocked content cannot be cited.
Question 2: Are you comfortable with your content being used for model training? One guide frames this as a copyright and strategy choice, since you can close training bots while keeping answer bots open.
The Superblog guide leans toward openness for marketing content, saying blocking search and citation bots removes your blog from AI search results while competitors stay in, with no upside for marketing content. That is one publisher’s opinion and fits some sites better than others.
The “train-block, search-allow” pattern is spreading. Cloudflare data cited by one analysis shows PerplexityBot now appearing in Allow rules more often than Disallow, as sites begin distinguishing training from retrieval.
A 20-Minute Audit
- Open your robots.txt and list every rule that names an AI bot or uses a blanket disallow.
- Check your CDN, firewall, and security plugins for bot-blocking toggles.
- Review server logs for AI user agents. Some bots are polite, others are not: one guide suggests allowing all of them with the possible exception of misbehaving high-volume bots like Bytespider.
- Test key pages with the URL Inspection tool in Search Console, to confirm they are indexable with snippets allowed.
- Write down your policy so the next person who edits the file understands why each rule exists.
What Robots.txt Cannot Do
Robots.txt is a request, not a lock. Compliant bots follow it, others may not. For sensitive material, use logins or server-level controls. Also remember that user-initiated fetchers behave differently: one table in the Superblog guide marks ChatGPT-User as only partially respecting robots.txt, since it acts on a user’s request. superblog
Allowing access also doesn’t guarantee citations. Crawlers read your page, but the content still has to be useful, trustworthy, and relevant to earn a mention.
The Takeaway
AI visibility begins with access, and access is controlled by a handful of lines that many teams never review. Separate training from search, check the layers outside robots.txt, and record your policy.
If you want a second opinion on your setup, Sarkar SEO can audit your crawler rules, server logs, and indexation together, then recommend a configuration that matches your goals instead of copying a template.
