


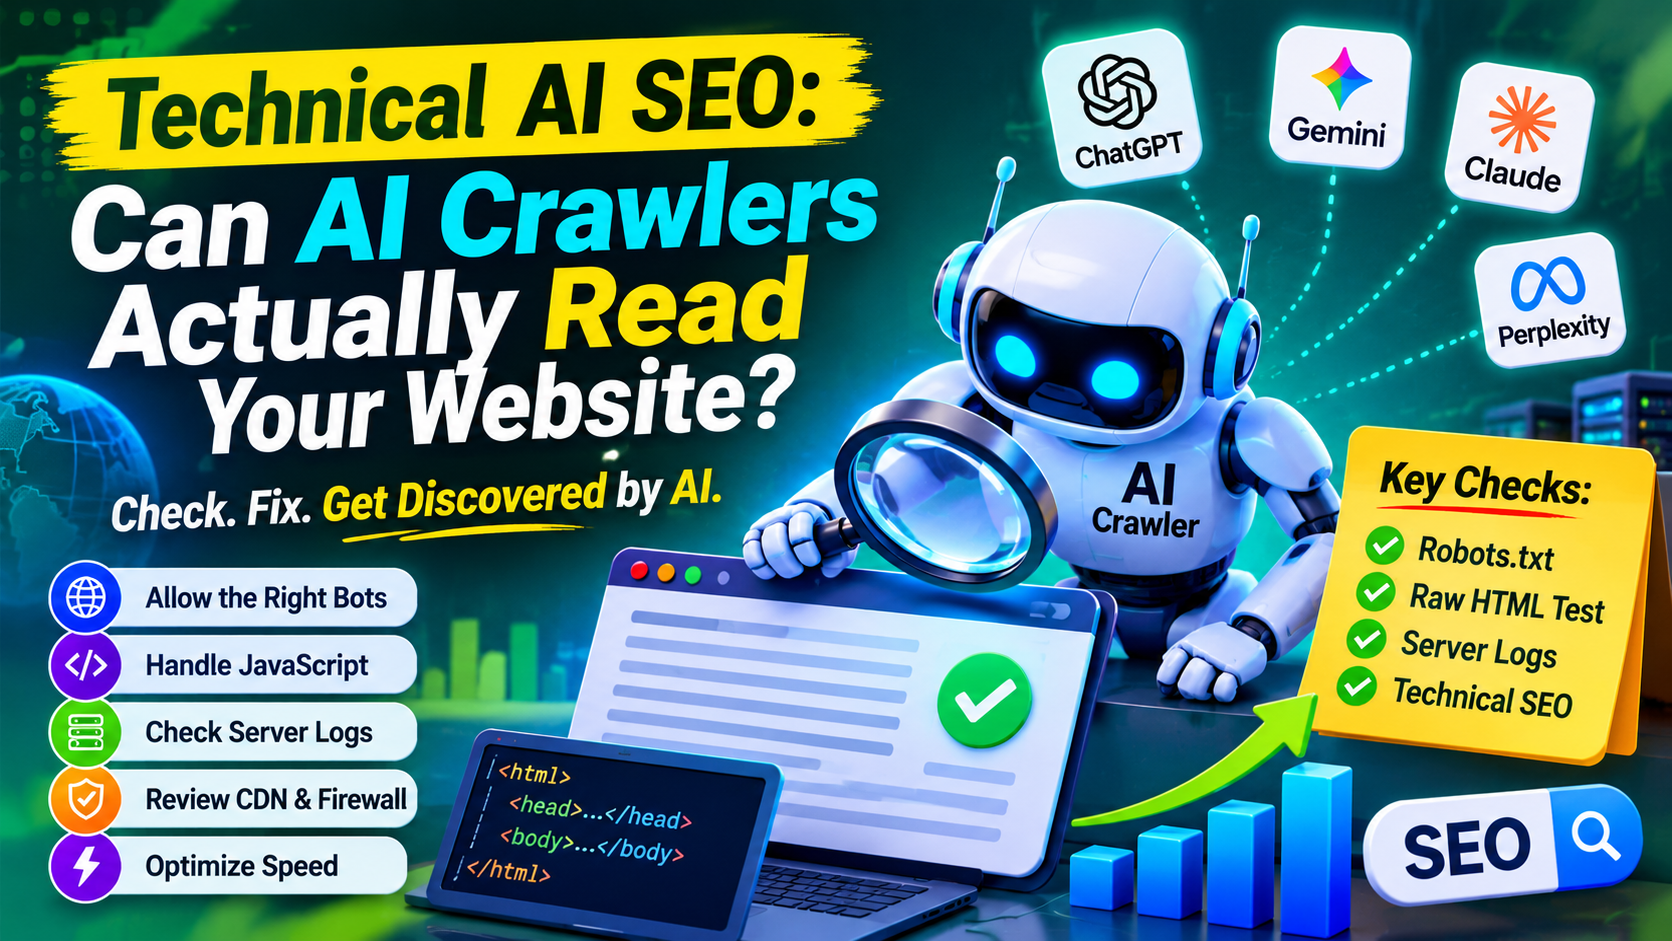
You can publish excellent content and still be invisible to AI SEO assistants if their crawlers can’t reach it or can’t read it. These failures are technical and silent, and they rarely show up in a normal analytics dashboard. This guide covers how to check for them.
Three Jobs, Three Kinds of Bot
“AI crawler” is not one thing. Sorting bots by job makes every later decision easier.
- Training crawlers collect content that may be used to build future models.
- Search crawlers build the index an assistant uses to find and cite sources.
- User-triggered fetchers open a page because a person asked an assistant about it.
OpenAI shows how this works in practice. OAI-SearchBot helps sites appear in ChatGPT search results, while GPTBot is a separate crawler for content that may train foundation models. ChatGPT-User visits a page when a user asks a question, and OpenAI says robots.txt rules may not apply to those user-initiated actions. Anthropic documents a similar split, and its search crawler and training crawler are separate controls. AI crawlers in robots.txt: GPTBot, ClaudeBot, and more +2
What Blocking Actually Costs
Many sites block “AI bots” wholesale, then wonder why they never appear in AI answers. The consequences differ by bot. Blocking GPTBot does not hide your site from ChatGPT search, while blocking OAI-SearchBot removes you from its answers.
Whether to allow training is a business and ethics decision, not an SEO one. Just make it deliberately. Also remember what robots.txt cannot do. User-triggered fetchers largely ignore it by design, so if you truly need to restrict them, you need a firewall rule, not a text file.
The JavaScript Blind Spot
This is the most overlooked problem. Google renders JavaScript, which hides a lot of sloppy front-end work. Other crawlers may not be as forgiving. A widely cited analysis by Vercel and MERJ found that GPTBot, OAI-SearchBot, ClaudeBot, and PerplexityBot take the HTML the server returns and move on, downloading JavaScript files without executing them.
Here is what that means for you. If your pricing table, FAQ, or product details load only after a script runs, a human and Googlebot may see a full page while a non-rendering crawler sees a shell. One agency illustrated the gap with a page showing 3,209 words to a human but only 28 words in raw HTML.
Treat this with some caution. That study dates from December 2024, one of the confirmations cited is secondary, and crawler behavior can change. Test your own pages rather than assuming either way.
The 10-Minute Raw HTML Test
- Open a key page, then use “view source” (not “inspect”). Source shows what the server sent before any script ran.
- Search the source for a sentence from your main content, your headline, and one FAQ answer.
- Repeat with a command-line request such as curl, which returns the same raw HTML a basic crawler would receive.
- If the text is missing, your content depends on client-side rendering.
The usual fix is server-side rendering or static generation, so the finished HTML arrives in the first response. Your developers will know the right approach for your framework.
Check the Logs, Not Just Analytics
Analytics tools won’t help here. Crawlers that don’t run your analytics JavaScript never appear as normal visits in GA4, so a healthy-looking dashboard can hide a problem. Server logs tell the truth. One practitioner recommends 30 to 90 days of logs showing which AI crawlers appear, which URLs they request, which status codes they receive, and how large the responses are. gofishdigitalmindgruve
Look for these patterns:
- No visits from a search bot you allowed. That suggests a block somewhere between the bot and your server.
- A high share of 403 or 429 responses. Your security layer may be rejecting legitimate crawlers.
- Tiny response sizes on important pages. That often means an empty rendering shell.
- Heavy requests to useless URLs. Filters, session parameters, and duplicate paths waste crawler attention.
The Hidden Layer: Your CDN and Firewall
A page can pass the robots.txt test and still be unreachable. Google’s own guidance reminds site owners to confirm that crawling is allowed in robots.txt and by any CDN or hosting infrastructure. Bot-protection tools are often configured years before AI crawlers existed, and some treat unfamiliar user agents as threats. Review your rules, then confirm with log data that the bots you want are getting through. Verify bots against the operator’s published documentation, because user-agent strings can be faked.
A Note on Speed
Some research ties faster pages to more citations. One write-up cites a study of 129,000 domains in which pages with First Contentful Paint under 0.4 seconds were cited roughly three times more than pages above 1.13 seconds. Treat that as correlation, not proof. Fast pages tend to be well-built pages overall. Still, a lean server-rendered page helps humans and machines alike.
A Reality Check
Being readable is necessary, not sufficient. A perfectly crawlable page can still go uncited if it says nothing original or lacks credibility. Technical access gets you into the pool of candidates. Content quality decides who gets chosen. Any agency promising guaranteed citations from a configuration change is overselling.
Putting It Into Practice
A sensible sequence is:
- Decide your training policy, and write it down.
- Allow the search bots you want to appear in.
- Run the raw HTML test on your top ten pages.
- Review CDN and firewall rules.
- Pull 30 days of logs and read them.
This kind of crawl-level audit is the foundation of Sarkar SEO’s technical reviews, because content improvements are wasted when machines can’t reach the page. Sarkar SEO also suggests repeating the check after every redesign, migration, or security-plugin change, since those are the moments access quietly breaks.
If you’d like an experienced second look at how AI systems see your site, Sarkar SEO can run the audit and give you a prioritized fix list.
